Architecture
TraceAgent follows a client-server architecture with a modular package design. Understanding how the pieces fit together helps you make the most of the platform.
System Overview
Package Breakdown
TraceAgent SDK
The core Python client. Use it to:
- Start and finish runs — Create named sessions with descriptions
- Record file operations — Reads, writes, patches, and diffs
- Record commands — Shell executions with exit codes
- Record tool calls — Custom tool invocations with parameters and results
- Attach artifacts — Any derived output from the agent
The SDK communicates with the server via REST API calls.
TraceAgent LangChain
A callback handler that plugs into LangChain's callback system. Once attached, it automatically captures:
- Chain starts and completions
- LLM calls (prompts and responses)
- Tool usage and results
- Retriever activity
- Error states
No manual instrumentation needed — just pass the callback.
TraceAgent Pydantic AI
A capability for Pydantic AI 2.x agents. Add it to your agent and it records model calls and tools without blocking the agent. See Pydantic AI Integration.
TraceAgent Server
The FastAPI backend that persists and serves trace data:
- Receives events from the SDK, the LangChain handler and the Pydantic AI capability
- Receives OpenTelemetry traces at
POST /v1/traces - Stores data in SQLite (default) or PostgreSQL
- Exposes REST API for the UI to query
- Supports audit metrics collection
TraceAgent UI
The interactive dashboard for visualizing traces:
- Execution timelines with event details
- Run listings with search and filtering
- File diff viewer for recorded edits
- Artifact browser
Data Flow
- Your agent code calls the SDK (or uses the LangChain callback or the Pydantic AI capability)
- The integration sends events over HTTP to the Server
- The Server persists events in the database
- The UI queries the Server API and renders visualizations
The server also exposes an OTLP/HTTP receiver at POST /v1/traces. Spans that follow the GenAI conventions are turned into the same runs and events as the SDK and framework integrations, so agents can be traced without TraceAgent code. See OpenTelemetry Ingestion.
What a Run Shows
A run shows what the agent actually did, not just a list of events. Each run records the provider, the model and the token usage of its model calls.
Tools appear under the agent step that used them, so the timeline is nested: the agent run contains its model calls and tools, in the order they happened, and nested agents appear inside the step that called them. The inspector shows what happened in plain terms (result, duration, tool, tokens, error) and keeps identifiers and raw data under "Technical details".
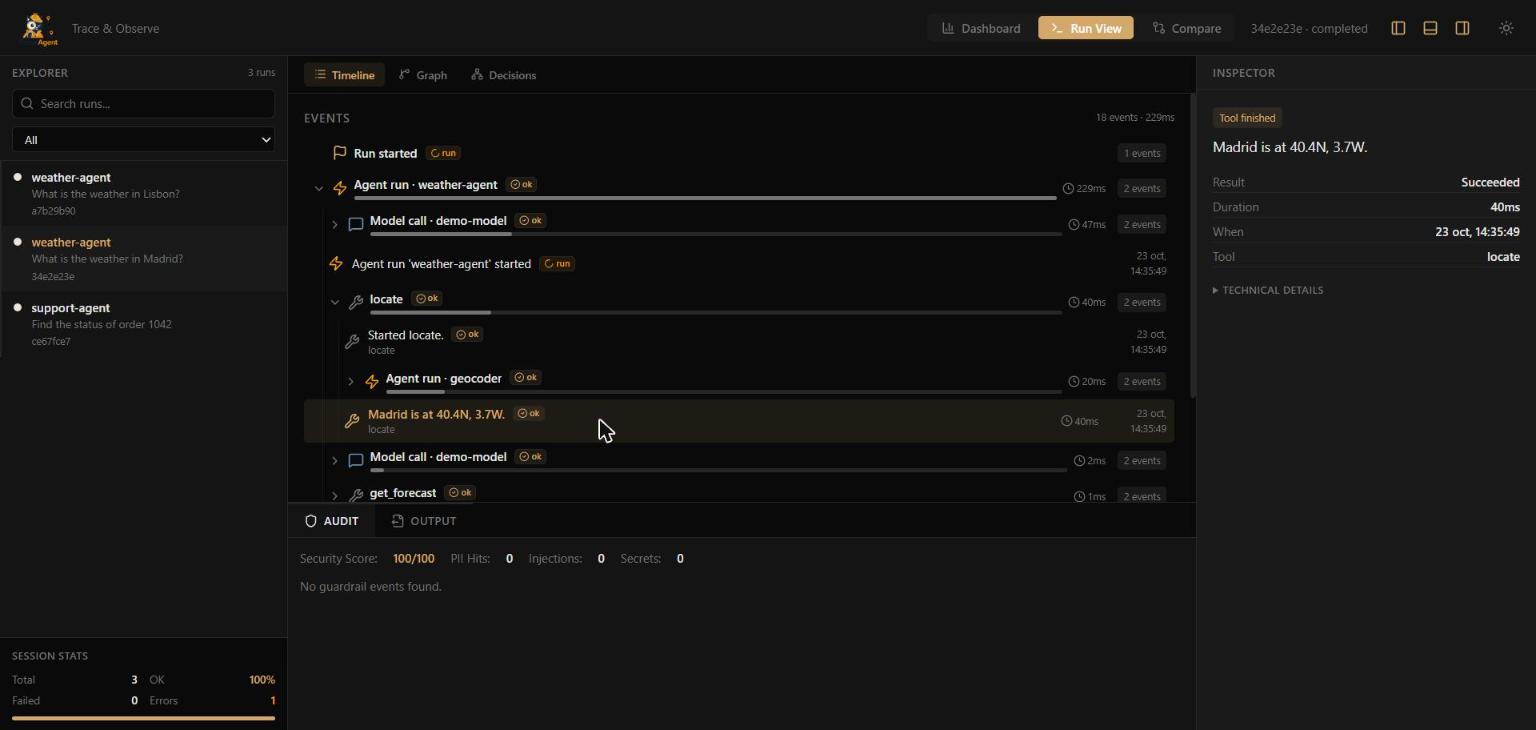
When a run finishes or fails, TraceAgent derives its decisions (which tool was chosen, retries, recoveries) and flags such as loops. They are not shown while the run is still running. Each decision lists the events it is based on.
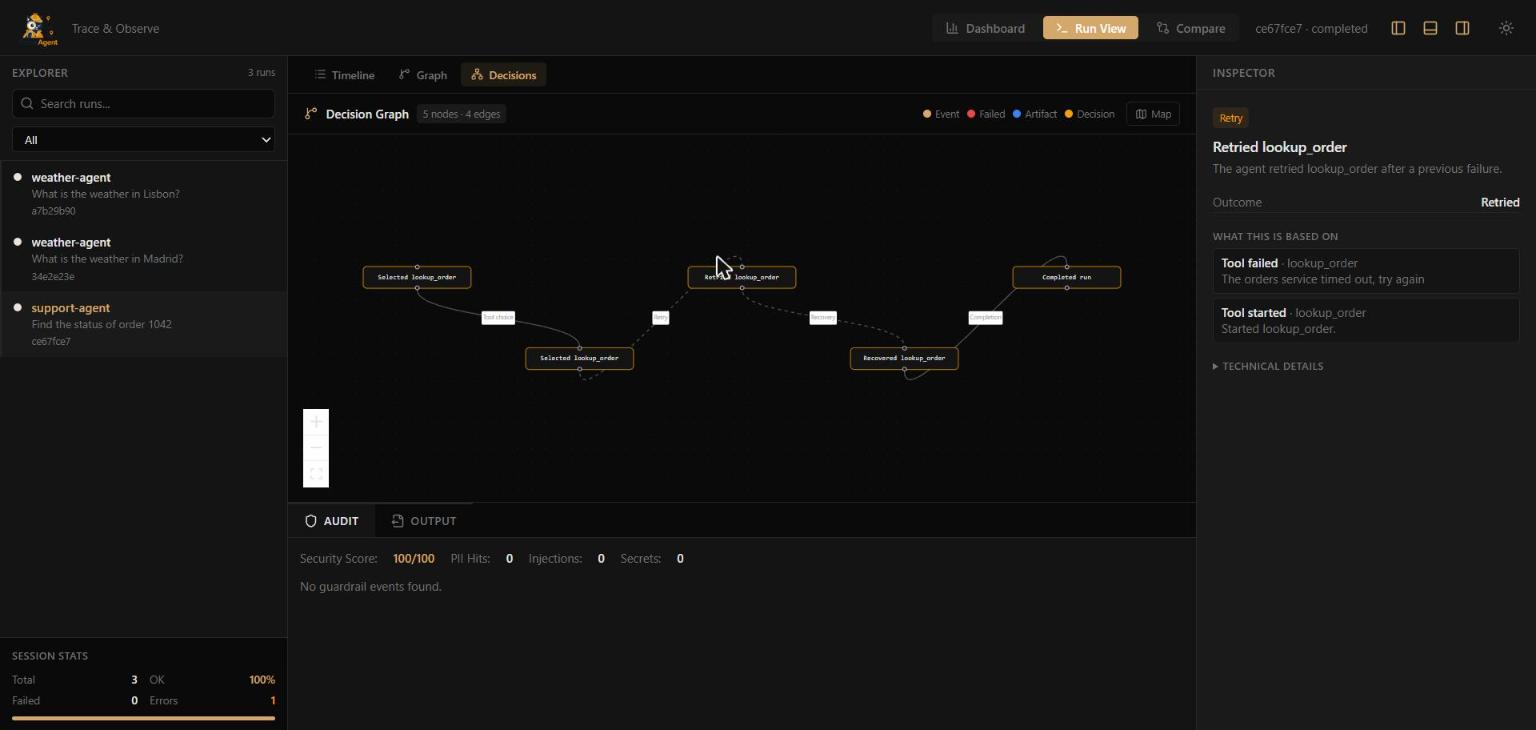
The UI updates live while the agent is running.
All data stays on your infrastructure. There's no external telemetry, no cloud dependency. You own everything.
What's Next?
- SDK Reference — Instrument your agent
- Configuration — Customize the setup